

Start Your Project Today
Tell us about your project — we’ll get back within 24 hours

Founder
User Interface Design
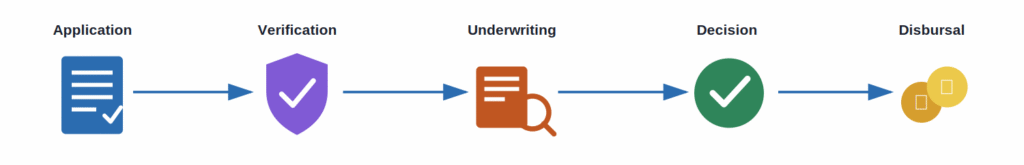
The loan origination process covers every step between a borrower submitting an application and funds actually reaching their account. It typically runs through five stages: application intake, identity and income verification, underwriting, the credit decision, and disbursal.
Each stage exists to answer one question before the next can begin. Intake confirms who is applying and for what, verification confirms the applicant is who they claim to be, underwriting assesses whether they can repay, and the decision stage applies credit policy to reach an approval or denial.
Loan servicing is a separate discipline that begins only after disbursal, covering repayment tracking, collections, and account maintenance. Origination and servicing are often built as connected but distinct systems, since the data each one needs and the users who interact with it are different.
For lenders operating in India, origination is not just a workflow; it is a set of real-time data connections. Identity checks pull from the Central KYC Records Registry, income assessment often draws on GST returns, ITRs, or account aggregator data, and every disbursal has to route through bank rails with a compliant e-mandate setup, a set of connections most teams end up building as part of the same KYC and AML module that handles onboarding elsewhere in the product.
Skipping any one of these integrations does not simplify the build; it just moves the missing check to a manual step later, which slows the process down rather than removing work from it.
Each data source also has its own response-time and availability characteristics that the origination system needs to account for. A bureau pull typically returns within seconds, while GST or ITR-based income verification can take longer depending on the filing source, so the workflow has to handle both without stalling the entire application on the slowest step. Key Fact Statement generation and audit-trail requirements are usually where this connects to broader regulatory technology infrastructure rather than being a one-off origination feature.
A manual or partially digital origination process depends on staff re-entering the same borrower data across multiple systems. Every re-entry point is a place where a file can sit untouched for a day or longer while someone gets to it.
Financial institutions in India are already moving away from this model. EY’s research on Indian financial services found that most financial firms have either deployed the technology in at least one use case or plan to pilot it within the next year, with a large share expecting it to meaningfully improve efficiency across their operations.
The cost of these delays is not just borrower frustration. A slower origination cycle also means a lender’s underwriting team spends more time chasing documents than actually assessing risk, and a longer time-to-decision gives a borrower more opportunity to accept a competing offer elsewhere before the original application is even processed. How much of this gets fixed usually comes down to engineering scoping done well before the first line of code is written, not the automation tooling itself.
| Approach | Typical timeline | Control over credit policy | Best fit |
|---|---|---|---|
| Custom build | 6 to 12 months | Full: every rule, integration, and workflow owned in-house | Lenders with distinct underwriting models and long-term engineering capacity |
| SaaS LOS | 4 to 8 weeks | Limited: configuration within the vendor’s existing rule engine | Lenders prioritizing speed over deep customization |
| Configurable platform | 2 to 4 months | Moderate: business teams configure rules, engineers extend the rest | Lenders wanting configurability without a from-scratch build |
Most origination failures surface after go-live, not during development. The individual stages work in isolation during testing, but production traffic exposes gaps between them that a controlled test environment rarely reveals.
Bureau and CKYC APIs occasionally return incomplete or delayed responses, and a build that assumes every response arrives instantly stalls the moment a provider has downtime. Underwriting rules that were hardcoded during development also become a bottleneck the first time a credit policy needs to change, since every adjustment then requires a full engineering cycle instead of a configuration change.
Handoffs between underwriting and disbursal are another common failure point. When the decision system and the disbursal system are built as separate modules without a shared status model, approved loans can sit unfunded simply because neither system knows the other is waiting on it.
Document verification is a third common gap. Automated OCR and validation checks handle standard formats well, but edge cases, such as scanned documents at odd angles or non-standard salary slip formats, still need a manual review path. A build that assumes every document will pass automated checks on the first attempt ends up routing more exceptions to manual review than the team expects.
Most integration problems show up after launch, not during development. The framework itself is standardized, but participation across banks and account aggregators is not.
A single account aggregator is not connected to every bank. A customer’s savings account might sit with one while their insurer only connects through another, which breaks a single-consent experience into multiple approvals. Consent screens that bury purpose and duration in fine print also drive higher abandonment than any technical failure does.
Data arriving structured but unparsed catches many teams off guard as well. The account aggregator delivers a machine-readable file, not a categorized summary, so a lending team still needs a parsing and categorization layer before that data becomes usable in an underwriting model. Skipping this step is a common reason integrations look complete in a sandbox but stall once real transaction data starts arriving in production, a gap that usually traces back to how the surrounding fintech software development was scoped in the first place.
Most origination builds fail at the seams between stages rather than within any single stage. Zethic designs the underwriting-to-disbursal handoff as a shared state machine from the start, so an approved decision triggers disbursal automatically instead of waiting on a manual status check between systems. Document exception handling gets the same upfront attention, with a defined manual-review path built in from day one rather than patched on after the first batch of edge cases arrives. For lenders weighing a custom build against a configurable platform, Zethic scopes the integration surface first: CKYC, bureau, and account aggregator connections, before committing to either path.
Let Zethic help you build smarter Not just faster
Delays usually come from gaps between systems rather than any single stage, such as bureau API downtime or a disconnect between the underwriting decision and the disbursal system, the same kind of gap that shows up in fraud detection in lending systems when checks run in isolation.
Ram brings deep expertise in product strategy and system architecture across fintech, SaaS, and AI platforms. He specializes in pre-execution planning to help teams build scalable technology foundations and avoid costly rebuilds.

Adding {{itemName}} to cart
Added {{itemName}} to cart