

Start Your Project Today
Tell us about your project — we’ll get back within 24 hours

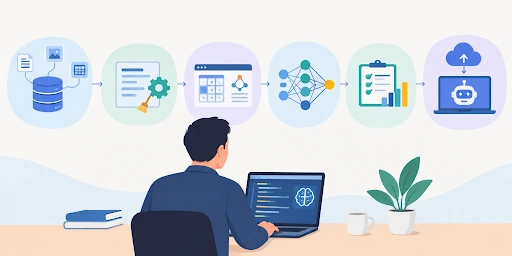
Teams often picture the machine learning development process as a straight line: gather data, train a model, ship it. Then a stage they assumed would be simple turns into the one that stalls the whole project for weeks. The stages themselves are well documented, but almost nobody tells you upfront where the process breaks down, how long each part really takes, and who needs to be in the room when it does.
Traditional software runs on rules a programmer writes by hand, work that most artificial intelligence service providers still build alongside their machine learning projects. Machine learning flips that. Instead of coding the rules, you feed a model examples and let it work the rules out for itself.
That flip changes what “done right” looks like. Ship buggy code and the bug is usually visible quickly. Ship a model trained on data that quietly misrepresents the real world, and everything can look fine for months before it fails.
That’s the entire reason the machine learning development process treats data quality as the main event, not a chore to rush through before the “real” work starts.
Seven stages, on paper. In practice, projects circle back through earlier ones constantly, so treat the list below as a map, not a straight road. Google’s own ML development phases group this same work into four broader phases, but the underlying idea, iterate rather than march straight through, is identical.
| Stage | What Happens | Typical Duration |
| Problem framing | Translating a business goal into a specific, measurable prediction task | 1-2 weeks |
| Data collection | Gathering the raw data needed to train and test the model | 2-6 weeks |
| Data preparation | Cleaning, labeling, and structuring the data into a usable format | 3-8 weeks |
| Model training | Selecting an algorithm and fitting it to the prepared data | 2-6 weeks |
| Evaluation | Testing the model against data it has not seen, to check real accuracy | 1-3 weeks |
| Deployment | Integrating the trained model into a live business system | 2-4 weeks |
| Monitoring | Tracking accuracy in production and flagging when retraining is needed | Ongoing |
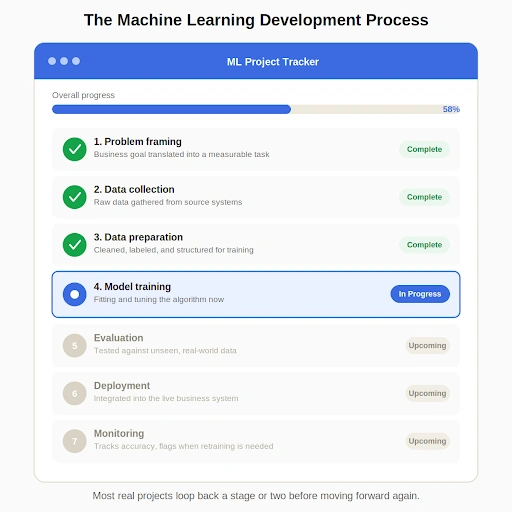
Look at that table again: data preparation is where timelines get rewritten. With clean, well-labeled historical data, a business can move through it in a few weeks. With data scattered across five disconnected systems, this one stage alone can eat more time than every other stage combined.
Model training tends to surprise people the other way. Once the data is ready, fitting and tuning a model is often quicker than getting the data ready was. The stage that sounds the most technical is rarely the one holding up the calendar.
Every process like this has a few predictable failure points, and knowing them beats memorizing any checklist. Evaluation is the big one: a model can post great numbers on training data and still fall apart the moment it meets real, messy, unseen examples.
Here’s a costly assumption: every stage needs the same caliber of specialist. It doesn’t. Problem framing is won or lost by someone who understands the business, full stop, not necessarily anyone with deep ML credentials.
Data engineering and general software skills carry most of the data collection and data preparation. Model training and evaluation are where you need machine learning expertise specifically. Deployment swings back toward regular software and DevOps skills, and monitoring lives somewhere in between.
Staff every stage with a senior ML specialist and you’re overpaying. Staff none of them with one, and you’ll end up with a model that never quite works right. This is the same calculation behind the in-house vs outsourced AI development decision, just applied stage by stage instead of to the whole project at once.
Missing stakeholders derail this process about as often as bad code does. Problem framing needs a business owner at the table, not just engineers, because a technically flawless model built on the wrong problem is still a failed project. A business without a technical co-founder often fills that gap with a fractional CTO, someone who can sit in the room for problem framing without a full-time hire.
Data preparation goes better with a domain expert nearby, someone who spots a mislabeled field before it teaches the model a bad assumption. Come evaluation and deployment, pull the business owner back in to confirm the model solves the original problem, not just whatever metric the team happened to chase.
No version of this process skips the slow parts. What’s realistic instead is knowing in advance which stage will drag for your specific data, staffing each one with the right mix of specialist and generalist talent, and keeping the right people in the loop right where things tend to go sideways.
Zethic works with founders and CTOs to do that planning before a project starts: mapping which stage will likely take the longest for a given dataset, scoping the right talent mix stage by stage, and keeping business stakeholders looped in at the points where the process tends to break down. Zethic builds the resulting project plan around a realistic timeline instead of an optimistic one.
Ram brings deep expertise in product strategy and system architecture across fintech, SaaS, and AI platforms. He specializes in pre-execution planning to help teams build scalable technology foundations and avoid costly rebuilds.
